

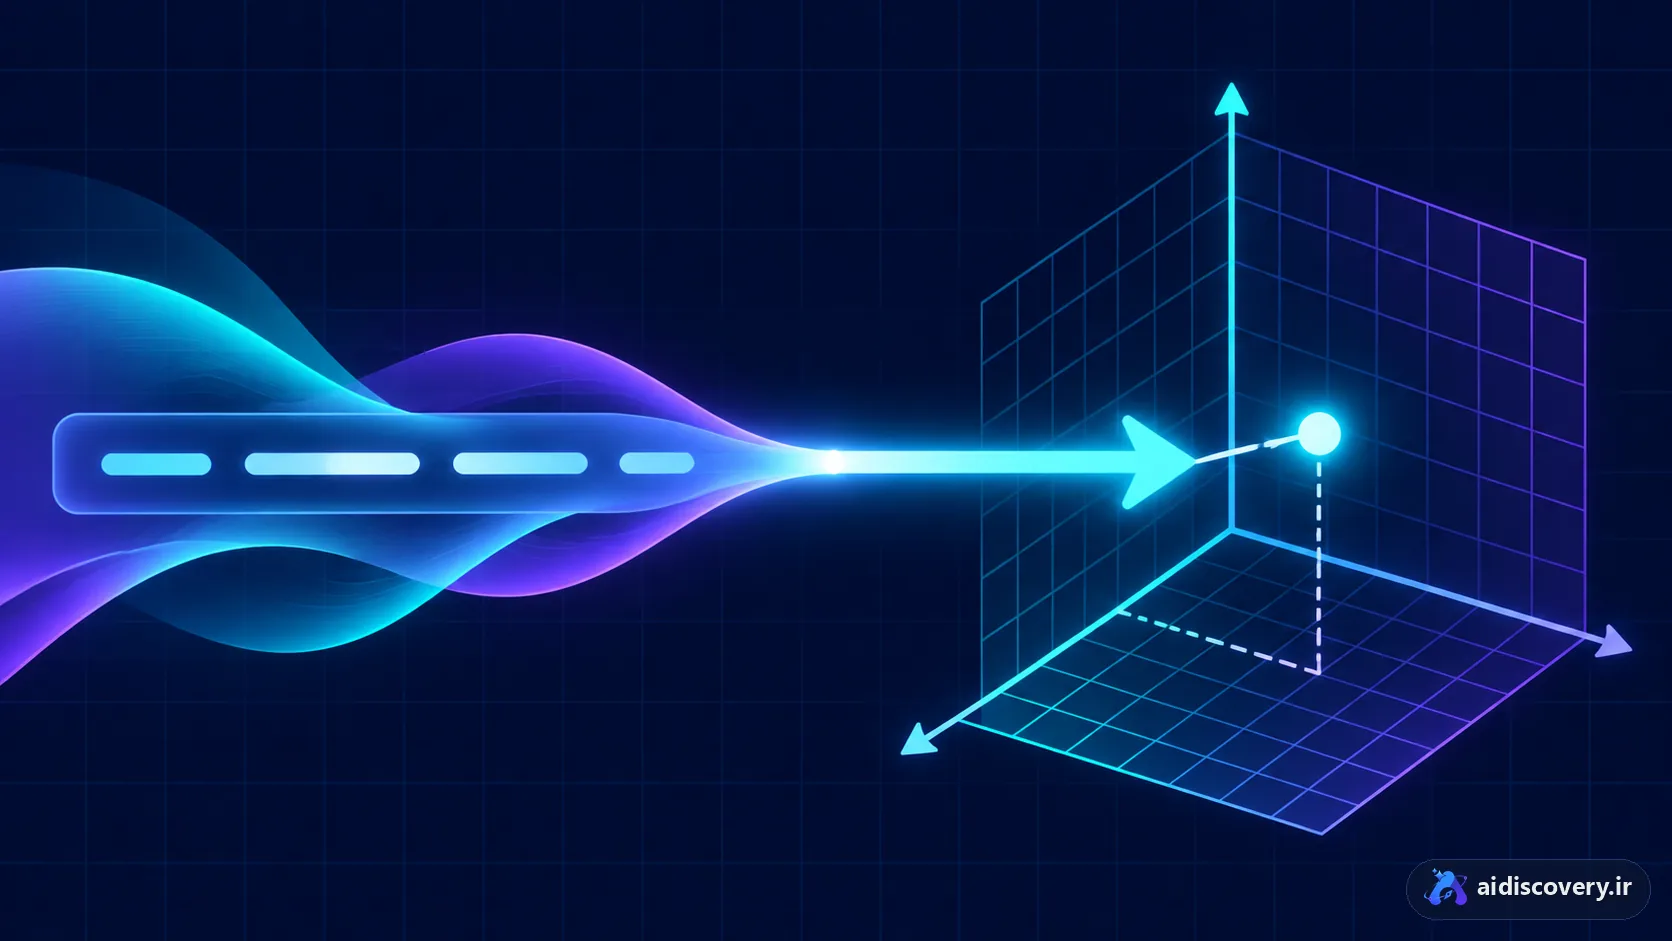
An embedding is meaning translated into numbers: a chunk of text (or an image) becomes a vector of thousands of numbers so that close concepts land on nearby vectors. “Cat” and “kitten” are neighbors; “cat” and “invoice” are not.
That simple trick is the substrate of half of applied AI: semantic (not keyword) search, RAG, recommenders, document clustering and duplicate detection. Specialized models like BGE and OpenAI embeddings do exactly this.
Daily-life use: whenever search matches your casual phrasing rather than exact keywords, embeddings are at work.